

AI Document Metadata Extraction Data Indexing Data Enrichment
Automatically extract and enrich document metadata with AI. elDoc transforms document content into structured information for classification, indexing, organization, and retrieval at scale
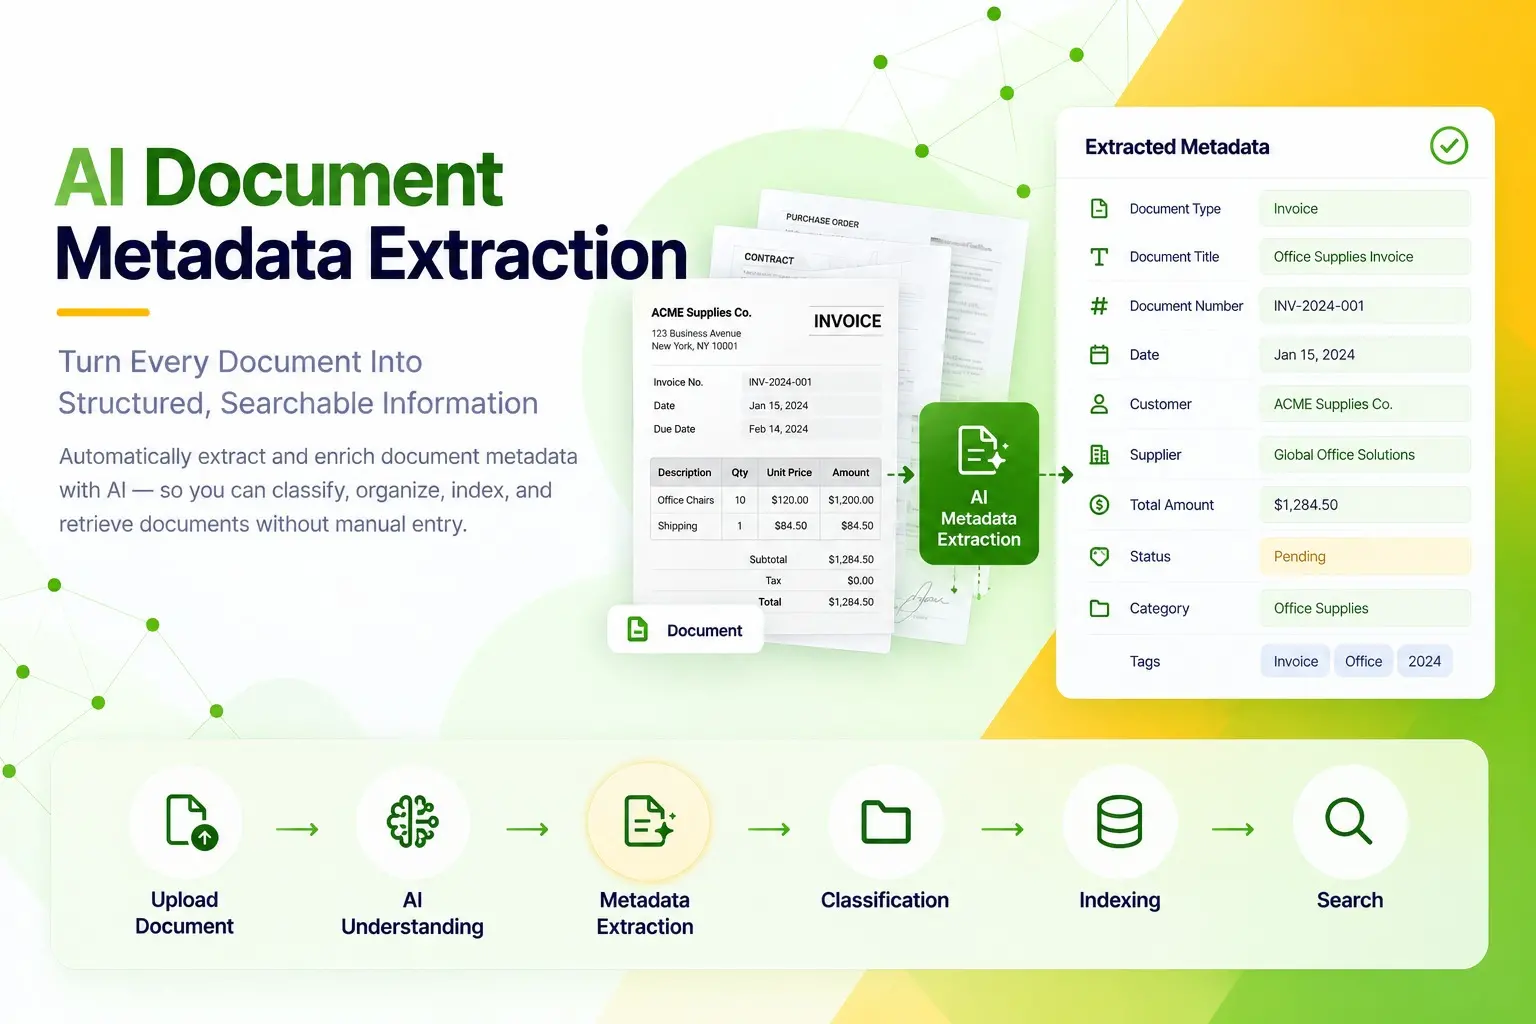
AI Metadata Extraction
Turn Every Document Into Structured, Searchable Data
elDoc uses AI to automatically identify, extract, and enrich document metadata — creating structured information for classification, indexing, organization, search, and downstream automation
Build the Context AI Needs
Extract the Data. Enrich Documents with Business Context
Automatically extract key information and enrich documents with structured metadata—adding the business context needed for more consistent indexing, organization, and downstream processing
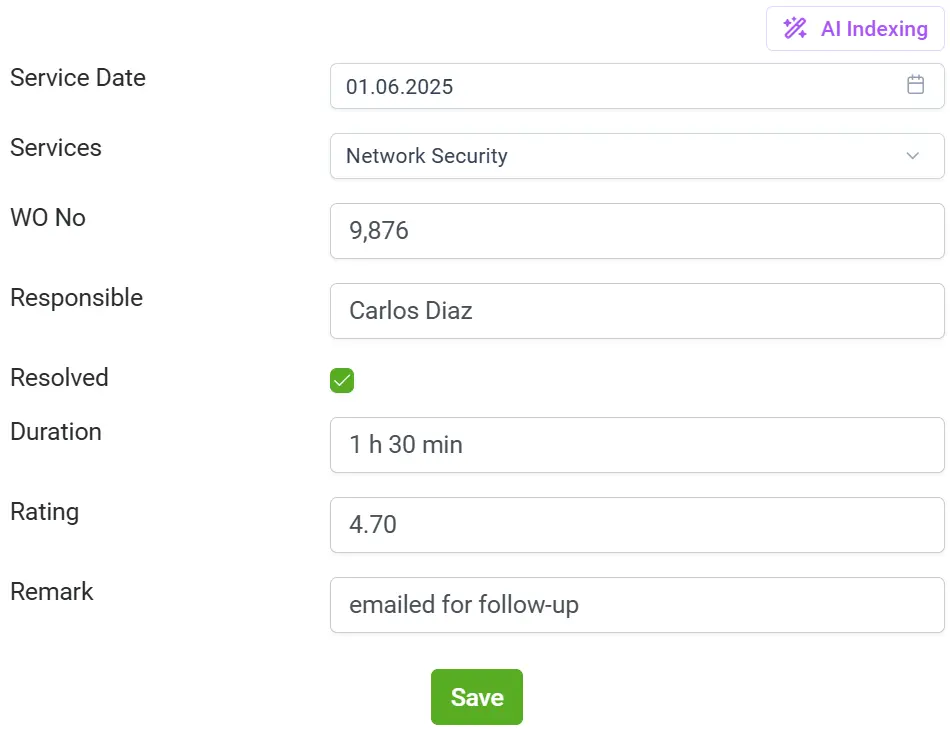
Scale Without Manual Effort
Index at Scale. Turn Millions of Documents into Structured Data
Automatically index high volumes of documents with AI. elDoc extracts and structures key metadata during migrations, bulk uploads, and archive ingestion — creating consistent, searchable document repositories
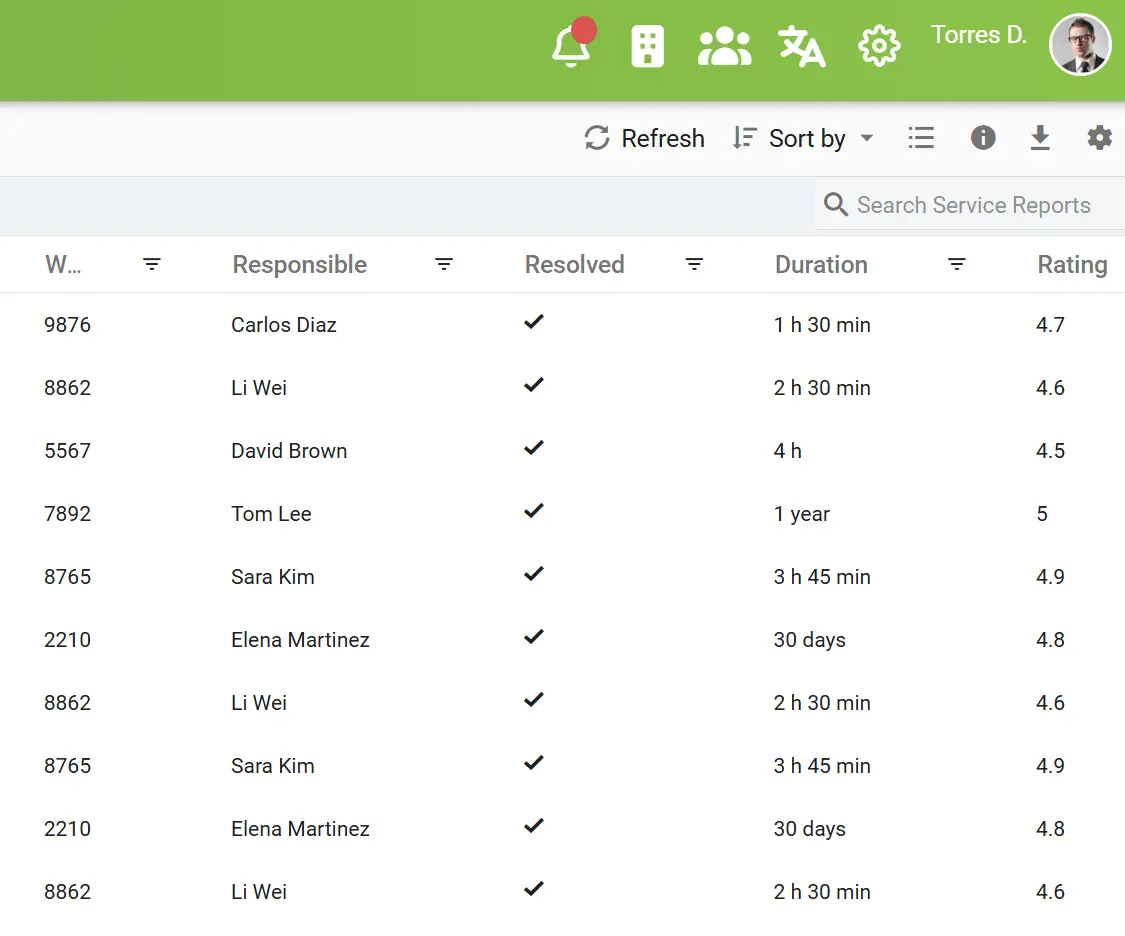
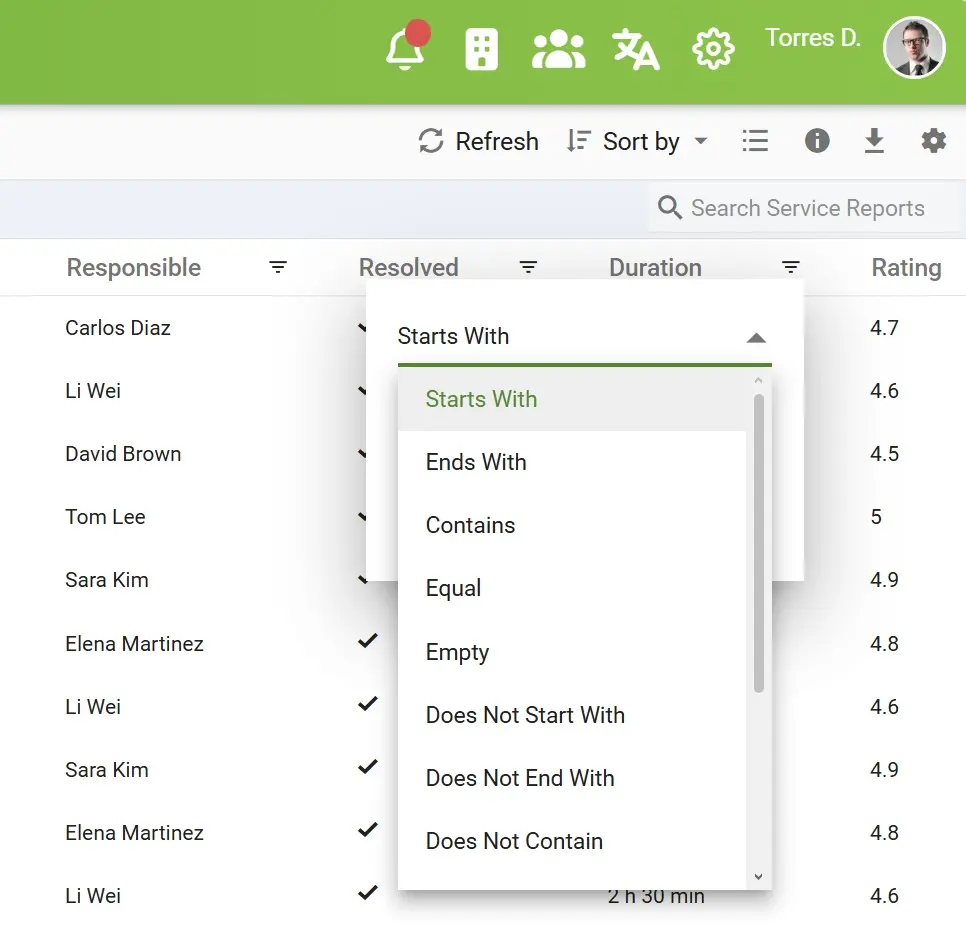
Filter. Structure. Export.
Turn Metadata into Actionable Information
Instantly filter and structure documents using multiple metadata criteria. Refine large datasets, identify exactly the records you need, and export structured metadata in CSV or JSON for reporting, analysis, system integration, or downstream processing
FAQ - AI Metadata Extraction Explained
Get answers to common questions about AI metadata extraction in elDoc — from extracting metadata from unstructured documents to automated indexing, custom fields, AI Search, and metadata export
1. Can elDoc extract metadata from unstructured documents?
Yes. elDoc can analyze unstructured document content and context to identify relevant information even when documents do not follow predefined forms, templates, or layouts
2. Can I define which metadata should be extracted?
Yes. Organizations can define the metadata fields required for different document types and business processes, allowing extraction to align with their specific information architecture
3. How is AI metadata extraction different from OCR?
OCR converts text from scanned documents and images into machine-readable content and serves as the first automated step in elDoc. AI metadata extraction goes further — understanding that content, identifying relevant information, and transforming it into structured, usable metadata for indexing, search, and downstream processing
4. Can extracted metadata be enriched with information not available in the document?
Yes. elDoc can enrich extracted metadata with additional business context from connected data sources, systems, or predefined business rules. This can extend document metadata beyond what is explicitly contained in the document — for example, adding customer attributes, categories, organizational data, reference information, or other relevant context
5. Can extracted metadata be exported?
Yes. Structured metadata can be exported in CSV and JSON formats for reporting, analysis, migration, integration, and downstream processing
6. Can elDoc automatically index large document repositories?
Yes. AI-powered metadata extraction can support high-volume indexing during document migrations, bulk uploads, archive ingestion, and ongoing document processing — reducing the need for manual indexing
7. Does metadata extraction require predefined document templates?
Not necessarily. AI can analyze document content and context without relying exclusively on fixed templates, which is particularly useful for diverse and unstructured document collections
8. Can AI metadata extraction work with any document type and layout?
Yes. elDoc can extract metadata across different document types, formats, and layouts — from contracts, invoices, purchase orders, and forms to reports, legal documents, correspondence, certificates, financial records, and technical documentation, including both structured and unstructured documents
See elDoc AI Metadata Extraction in Action
Discover Metadata Extraction at Enterprise Scale
Schedule a demo and see how elDoc automatically extracts, enriches, and indexes metadata at scale — turning millions of documents into structured, business-ready information
Let's get in touch
Want a closer look? Message us to arrange your demo
Get your questions answered or schedule a demo to see our solution in action — just drop us a message